Settings and costs
Tune what a knowledge base returns and how it is indexed, see what a change will cost before you save it, and cap what a base can spend in a month.
A knowledge base's Settings decide two things: what a search returns, and how the base is indexed. The first kind applies to the next search and costs nothing to change. The second rebuilds the index, so Synapse prices it before you save. Harbor & Pine's Compliance guides runs on a few changed settings, and every one of its costs shows under Costs.
Open the settings
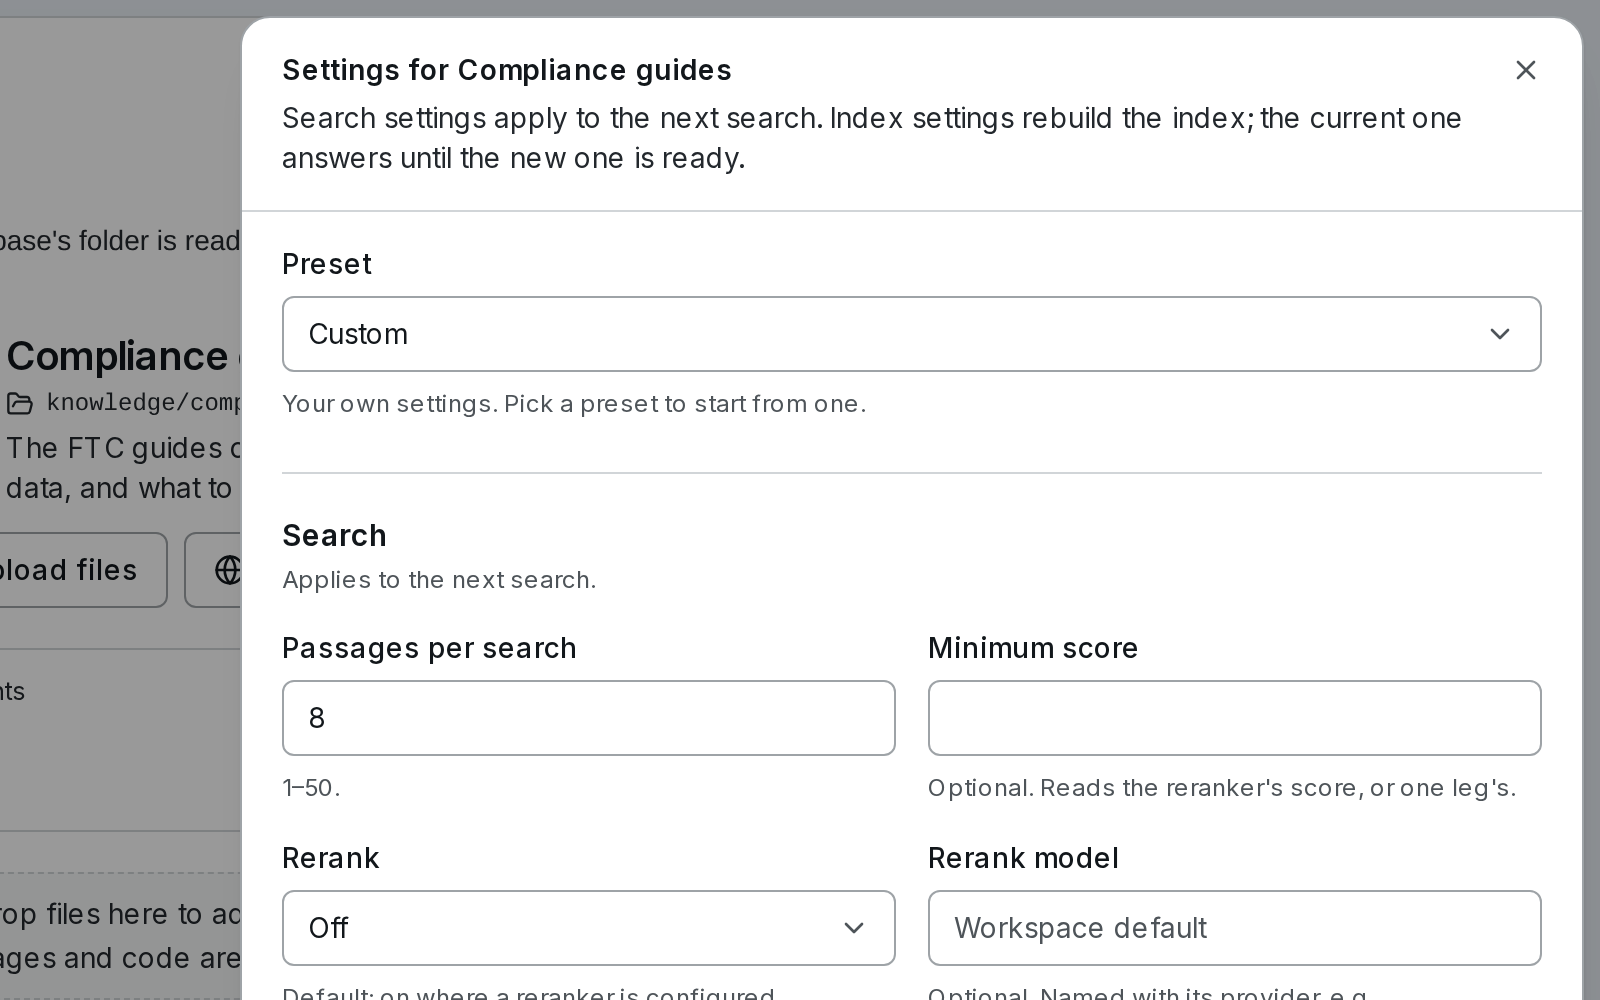
Open Knowledge, choose Compliance guides and press Settings. The drawer starts with a Preset — Cheap, Balanced or High recall — and shows Custom once any setting differs from one, as here, where rerank is off. Below it come three groups.
Search — applies to the next search
| Setting | Default | Change it when |
|---|---|---|
| Passages per search | 8 | Answers miss a passage that ranks just below the cut, or an agent's context fills up |
| Minimum score | None | Weak passages reach the agent for questions the base cannot answer |
| Rerank | Default | On or Off decides for this base; Default reranks where a reranker is configured |
| With neighbouring passages | No | A passage needs the one before or after it to make sense — or its whole section |
| Context limit (tokens) | 6,000 | How much passage text an agent gets from one search |
| Keyword weight / Meaning weight | 1 / 1 | Exact terms — part numbers, clause names — matter more than meaning, or the reverse |
Fusion and candidates holds the rest: how many passages each search brings back before fusion (50), and how many the reranker reads (50).
Index — changing these rebuilds the index
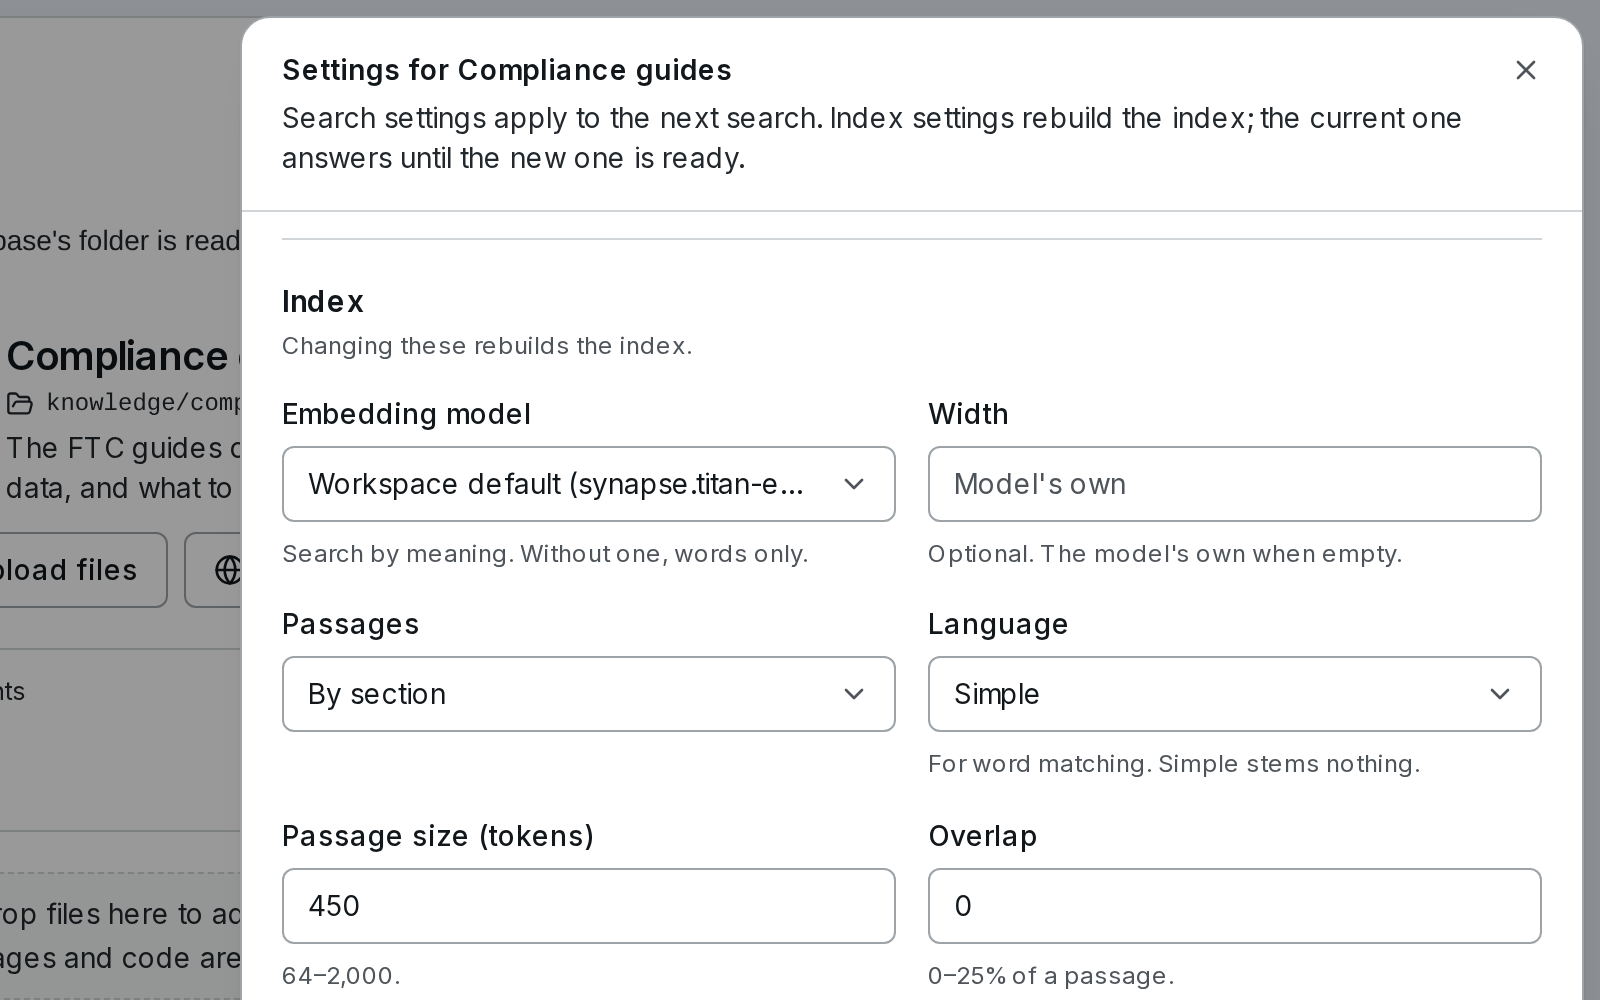
| Setting | Default | |
|---|---|---|
| Embedding model | Workspace default | What a search by meaning compares — see Embedding models |
| Passages | By section | By section cuts at headings and keeps tables whole; Fixed size, One per page or Whole document otherwise |
| Passage size (tokens) | 450 | Smaller passages are more precise; larger ones carry more context |
| Language | Simple | A stemming language matches forms of a word — terminate finds termination |
| Context for each passage | Title, date and section (free) | Contextual Retrieval has a model write a context for every passage instead |
Budget and access
Monthly budget (USD) caps what the base spends in a calendar month, and Visitors may search it lets widget and channel visitors search it. Both apply at once.
Change an index setting
Make the change
Change, say, Passage size from 450 to 300. The button becomes Save and rebuild, and the drawer prices the rebuild before anything is spent. For Compliance guides:
Saving rebuilds the index: 3 documents, about $0.0008. The current index keeps answering until the new one is ready. Embedding: 31,926 tokens with synapse.titan-embed-v2 — $0.0008
A line ends (your key) when a model on your own provider key will bill you instead of the wallet. If the price is more than the budget has left this month, it says the rebuild will pause at the budget.
Save and rebuild
The new index is built beside the old one, which keeps answering every search until the new one is ready and switches over. Files are not read again; only passages are cut and embedded again.
Check it found more
If the base has a question set, it runs again by itself after the switch, and Evaluate shows the change — hit@5 +7 points since the run before. See Evaluate.
If someone else saved the base while you had the drawer open, saving is refused with Someone changed this knowledge base since you opened it, so neither change is lost. Reload and make yours again.
What it costs
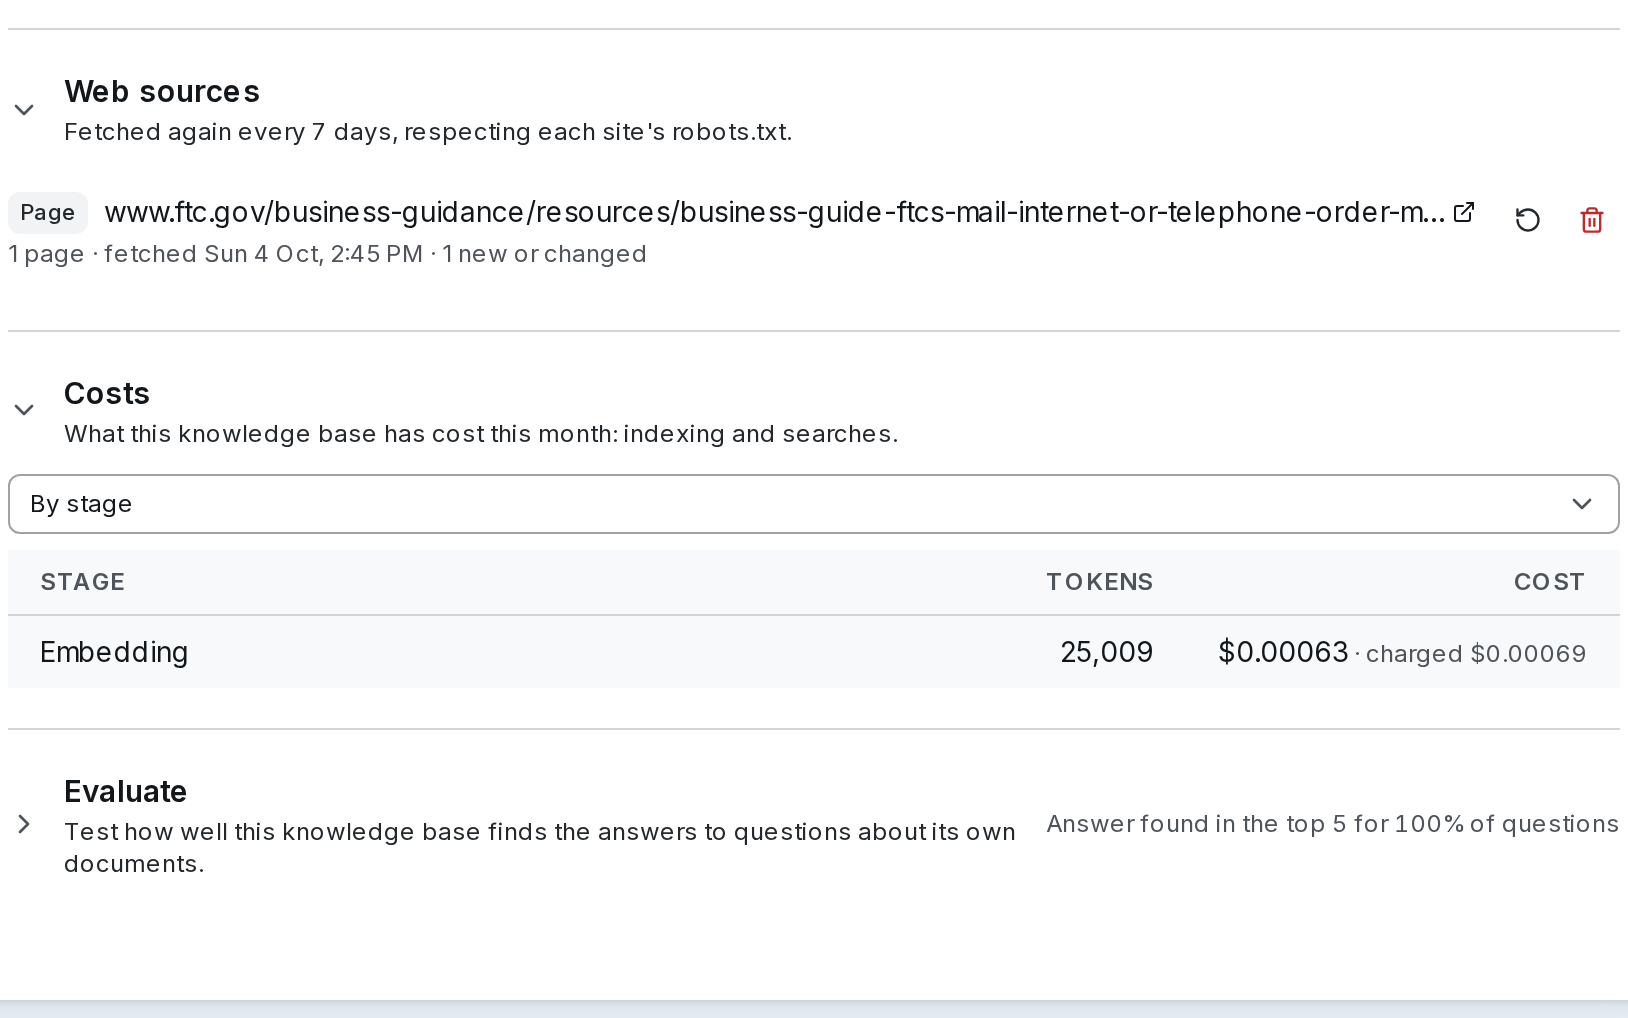
Costs, on the base's page, shows what it spent this month — by stage (Embedding, Reranking, Reading scanned pages, Context, and every search as one Searches line), or by day, document or model. On SynapseOrch Cloud each line shows what the wallet was charged beside the estimate. Each base's spend this month is also beside its folder in the list.
On SynapseOrch Cloud, Knowledge's default models are charged to the model wallet:
| Charged | |
|---|---|
| Embedding with Titan Text Embeddings v2 (the default) | $0.025 per million tokens |
| Reranking with SynapseOrch's reranker (the default) | $0.0025 per search |
| Reading a scanned page with Textract | $0.001875 per page read |
| Contextual Retrieval with Nova Lite | $0.075 per million input tokens, $0.30 per million output |
| A workflow's Retrieve or Ingest step | 0.1 credit |
There is no fee per search and no charge for the index itself, and reading files is free. A document embeds at roughly one and a half times its own token count. This month Compliance guides — two FTC guides and one web page — has embedded 24,834 tokens: $0.00062, well under a tenth of a cent. A model on your own provider key costs the wallet nothing; your provider bills you, and Synapse shows the estimate.
Cap it with a budget
Set the budget
In Settings → Budget and access, set Monthly budget (USD) — say 5 — and save. Costs then shows a meter: $3.20 left of a $5.00 monthly budget.
Know what happens at it
Synapse checks the estimate before each batch of work, not after:
- Indexing pauses. Waiting documents are Paused with Monthly budget reached; a rebuild pauses too.
- Searches carry on, by words only, with nothing charged, and say This knowledge base hit its monthly budget.
- Evaluate's searches count; a run that would cross the budget is refused before it starts.
Let it go on
Raise or clear the budget, or wait for the month (UTC) to turn, and everything goes on by itself, paying only for what it had not done.
On SynapseOrch Cloud a model wallet that can't pay pauses indexing the same way, with Model wallet can't pay, and it goes on within the hour of a top-up.
Contextual Retrieval
A passage cut from the middle of a document can lose what it is about: the seller must ship within thirty days — which seller, which rule? By default each passage is indexed after a line naming its document, date and section, for free. Contextual Retrieval has a model write a short context for every passage instead, which helps most when passages make little sense alone.
It costs one model call per passage — about $6 per 1,000 twenty-page documents with Nova Lite on SynapseOrch Cloud — and turning it on rebuilds the index, priced first like any rebuild. Measure it before and after with a question set: see Contextual Retrieval.
Self-hosted
The same settings and the same price-before-you-save. Your providers bill you directly, and Synapse estimates each cost from the Pricing reference on Runs › Usage; a local model costs nothing. A base embeds with Settings → Models → Knowledge → Embedding model for knowledge, or the workspace's own embedding model when that is empty, and reranks nothing until a reranker is chosen. See Costs and budgets.
Go further
- Search and Settings — every setting, embedding models, rerankers and rebuilds
- Costs and budgets — who pays, prices, the Costs section and budgets
- Contextual Retrieval — when it helps, what it costs, what we measured
- Knowledge API — price any settings without saving them
Search and citations
Follow one question through a knowledge base search — words and meaning, fusion, rerank, the cut — read its trace, narrow it with a filter, and check the citations an answer carries.
Evaluate a knowledge base
Keep a set of questions whose answers you know, measure how often a search finds them, and compare settings and indexes by a number instead of an impression.